

Table of Contents
- Step 1: Map Your Power Chain and Assess Risk
- Step 2: Build Data Centre Power Redundancy Strategies That Work
- Step 3: Apply Uninterruptible Power Supply Maintenance Best Practices
- Step 4: Maintain Backup Generators and Fuel Systems
- Step 5: Harden Cybersecurity Controls Across the Power Chain
- Step 6: Mitigate Human Error and Improve Operational Protocols
- Step 7: Plan Post-Outage Recovery and Root Cause Analysis
- Common Mistakes to Avoid When Preventing Data Center Power Outages
- Frequently Asked Questions
Last Updated: September 23, 2026
Step 1: Map Your Power Chain and Assess Risk
Preventing data center power outages starts with knowing exactly where your power comes from, where it flows, and where it can fail. Too many sites treat their power chain as a black box until something trips.
Conducting a Data Centre Electrical Infrastructure Audit
An infrastructure audit reviews every electrical asset on site, checking capacity, condition, and single points of failure:
- List every asset in the power chain, from mains intake to rack PDU.
- Record circuit capacity and current load on each feed.
- Note the age and service history of each item.
- Flag any single point of failure with no backup path.
- Check thermal conditions around switchgear and batteries.
Step 2: Build Data Centre Power Redundancy Strategies That Work
Data centre power redundancy strategies decide how your site behaves when one part of the chain fails. Good design keeps the load running. Poor design hands you a full outage.
- N+1 redundancy: one spare unit beyond what the load needs
- 2N: two complete, independent power paths
- Load balancing: spread demand so no single feed is overloaded
- Failover: automatic switchover when a primary source drops
N+1 Redundancy and Automatic Transfer Switch Configuration
An automatic transfer switch moves the load from a primary source to a backup when the primary fails, the hinge point of your whole power chain.
Step 3: Apply Uninterruptible Power Supply Maintenance Best Practices
Uninterruptible power supply maintenance best practices keep your UPS ready for the moment it matters. A UPS that has never been load-tested is a guess, not a safeguard.
Battery Testing, Firmware Updates and Load Balancing
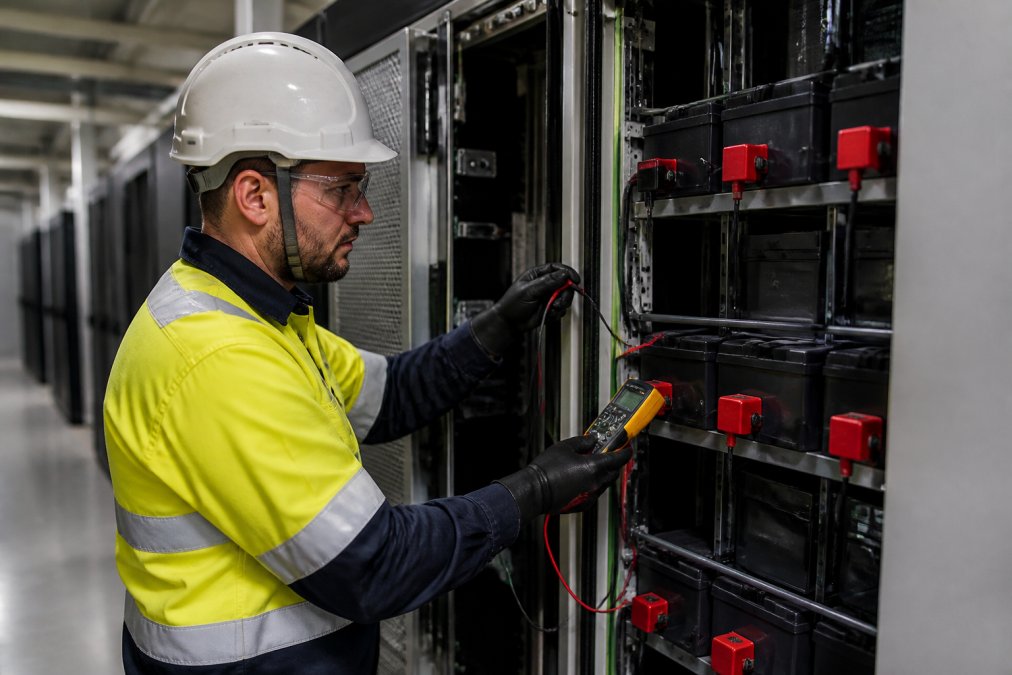
Batteries age faster than any other UPS component. Test them on a fixed schedule and replace weak strings before they fail.
- Run a load bank test at least once a year
- Check battery impedance and terminal torque
- Apply firmware updates to fix known faults and improve monitoring
- Rebalance loads across phases to avoid hot spots
Step 4: Maintain Backup Generators and Fuel Systems
Backup generators only work if someone maintains them. Fuel goes stale, filters clog, and starters seize when a set sits idle.
- Test fuel quality and top up tanks
- Check coolant, oil, and filter condition
- Exercise the automatic transfer switch alongside the generator
- Log every test result and review trends
Step 5: Harden Cybersecurity Controls Across the Power Chain
Modern power gear is networked. That connectivity brings real risk.
Apply these controls to every connected device:
- Segment management networks from office and guest traffic
- Enforce multi-factor authentication on remote access
- Patch firmware on a fixed schedule
- Log and monitor access to UPS and PDU interfaces
- Disable unused ports and services
Step 6: Mitigate Human Error and Improve Operational Protocols
Most outage post-mortems land on a person, not a part: a breaker pulled on the wrong feed, a firmware push during peak load, a transfer switch left in manual after a service visit. Human error is a process design problem, not a training problem. Four failure modes recur across mission-critical sites, each needing a different control:
- Wrong-asset action, a technician operates on the wrong circuit or device because labelling is ambiguous or out of date.
- Configuration drift, setpoints, transfer delays, or load thresholds are changed ad hoc and never returned to the documented baseline.
- Change-window pressure, work is rushed into a short maintenance window, so verification steps get skipped.
- Single-person dependency, one engineer holds the switching sequence in their head, and the site is exposed whenever they are unavailable.
Controls That Actually Reduce Wrong-Asset Action
Lockout and tagging is the floor, not the ceiling. The controls that move the needle make the wrong action physically or procedurally difficult:
- Unique, durable asset IDs on every breaker, PDU, and transfer switch, matching the single-line diagram exactly. If the label and the drawing disagree, the drawing loses.
- Two-person verification for any switching operation on a live path, one operates, one reads the schedule aloud and confirms the asset ID before the handle moves.
- Written switching schedules issued before the window opens, not improvised during it. The schedule names the asset, the from-state, the to-state, and the expected effect on load.
- Pre-task walkdown of the physical route, so the technician has already stood in front of the correct cabinet before the window starts.
Configuration Baselines and Change Control
Configuration drift is the quiet one. A transfer delay nudged from 10 seconds to 3 seconds during troubleshooting, never reverted, can drop the load on the next grid dip because UPS ride-through no longer covers it.
Vertiv™ EXS Series TOWER UPS →
- Capture a known-good configuration snapshot for every UPS, ATS, PDU, and generator controller after commissioning and after every approved change.
- Require a change record for any setpoint edit, with the reason, the approver, and the revert instruction.
- Run a quarterly configuration audit that diffs live settings against the baseline and flags every unexplained difference.
Drills, Documentation and Shift Handover
A response plan that lives in one person's head is a single point of failure. The fix is unglamorous:
- Run failover and switching drills on a fixed cadence, with staff who would actually be on shift during a real event, not just the day team.
- Keep a current runbook at the site and in a location reachable if the network is down, covering restore order, contact tree, and manual override steps.
- Use a structured shift handover that names any asset currently in a non-standard state (isolated, bypassed, in manual) so the incoming team is not surprised.
Step 7: Plan Post-Outage Recovery and Root Cause Analysis
Recovery speed and recurrence prevention are two different problems, and most sites conflate them. Recovery is a rehearsed sequence. Root cause analysis is a disciplined investigation. Doing the first well without the second guarantees you will run the same drill again next quarter.
Recovery: Restore in a Defined Order, Protect the Evidence
The first hour after an outage is when the most damage is done, to the load and to the evidence you need to understand what happened.
- Stabilise before you restore. Confirm the fault is cleared and the source is stable. Re-energising into a live fault turns a trip into equipment damage.
- Restore critical loads in a documented priority order. This order should be agreed before the event, not decided during it. Typical sequencing moves from life-safety and network core, to storage, to compute, to non-critical services.
- Capture logs and event data before anything is reset. UPS event logs, ATS transfer records, generator controller histories, BMS alarms, and PDU branch data all roll over or clear on reset. Export them first.
- Record a timeline in real time. Who did what, when, and what the readings showed. Memory reconstructs events badly within hours.
- Confirm steady state before standing the team down, stable voltage, stable load, no recurring alarms.
Resetting a device to clear an alarm destroys the event log that explains the alarm. Export first, reset second. This single discipline separates sites that learn from outages from sites that repeat them.
Root Cause Analysis: Separate the Trigger from the Cause
The most common analytical failure is stopping at the trigger. A breaker tripped, that is the trigger. Why it tripped, and why nothing caught it earlier, is the cause.
A workable framework for a mission-critical site:
- What happened, the observable event, with timestamp and asset ID.
- Trigger, the immediate action or condition that started the sequence (a fault, a command, a grid event).
- Contributing conditions, the latent weaknesses that let the trigger become an outage (an untested transfer, a stale baseline, an overloaded feed).
- Root cause, the underlying process or design gap that, if fixed, prevents recurrence.
- Detection gap, why monitoring or a human check did not catch it earlier.
Close the Loop: Actions, Owners and Dates
- Assign one owner per action, shared ownership is no ownership.
- Distinguish immediate fixes (restore redundancy) from systemic fixes (change the procedure or the design).
- Feed findings back into the risk assessment from Step 1: update the single-line diagram, the asset register, the configuration baseline, and the switching schedules.
- Re-test the affected path under load once the fix is in, so the correction is proven rather than assumed.
Standards Australia's electrical installation requirements set the compliance baseline for the physical work, but the recovery and RCA discipline is what turns a single incident into a permanent improvement.
Common Mistakes to Avoid When Preventing Data Center Power Outages
Preventing data center power outages comes down to discipline more than hardware. The mistakes we see most often:
| Mistake | Fix | Impact |
|---|---|---|
| No power chain map | Audit every asset and load | Finds hidden single points of failure |
| Untested redundancy | Run failover drills under load | Proves backup paths actually work |
| Stale generator fuel | Test fuel monthly | Prevents start-up failure |
| Unpatched firmware | Schedule updates | Closes known faults |
| No switching protocol | Enforce lockout and tagging | Cuts human error |
Frequently Asked Questions
What are the most common causes of data centre power outages?
Most outages trace back to a handful of sources: utility grid failures, UPS battery degradation, generator start failures, overloaded circuits, and human error during maintenance. Power quality issues such as voltage fluctuations and frequency drift also contribute. A data centre electrical infrastructure audit identifies which of these risks apply to your site and prioritises fixes.
How can redundant power systems prevent data centre downtime?
Redundancy means having a second path for power if the first fails. N+1 configuration adds one extra unit beyond what the load requires, so a single failure does not interrupt supply. Automatic transfer switches move the load between sources without manual intervention. Combined with a maintenance bypass panel, you can service a UPS without dropping the critical load.
What role does preventative maintenance play in power reliability?
Preventative maintenance catches failing batteries, loose connections, and firmware bugs before they cause an outage. Battery impedance testing, thermal imaging of connections, and scheduled firmware updates are core tasks. A written maintenance schedule with logged results gives you evidence of due diligence and helps predict component end-of-life before it becomes an emergency.
How can UPS systems be optimised to prevent unexpected power failure?
Start with correct sizing so the UPS runs in its efficient load range. Use online double conversion models for critical loads, enable ECO mode only where power quality is stable, and monitor battery health continuously. Remote monitoring software such as EcoStruxure IT can alert you to battery replacement needs and load anomalies before they escalate. Regular load banking confirms the UPS performs under real conditions.